PR throughput is not a business outcome
Amplitude's Pavan Kumar Patibandla on the gap between tripled PR throughput and the business, and what an always-on agent watching session replays catches.
Amplitude's PR throughput went up 3x this year. Whether ARR, adoption, retention, or time spent in the product moved at all is the question Pavan Kumar Patibandla asked out loud about his own company. He runs engineering there as VP of Engineering, and we talked about that gap at ELC 2026.
The loop Amplitude is trying to close: session telemetry becomes agent-readable context, the agent proposes a change, the change ships behind an experiment, and the business metric feeds back into what the agent watches next.
The 3x that stops at the PR
Patibandla's framing was blunt:
So if you notice what this year, like, even at Amplitude like when we had today, like we said, like, hey, there is a 3x improvement in the PR throughput. So we're actually doing 3x more as a company today. And that's probably true a lot of the companies in the Valley. But did all the ARR, did it go up 3x? Or like did the adoption of the product go up 3x? Or like, maybe we did the retention or the time spent on the product. So there is like divergence, right?
He thinks the 3x is probably true of a lot of companies in the Valley right now. From an engineering seat, a software factory stops at whether you can iterate on PRs, bugs, and on-call issues independently. The actual outcome for the business is adoption, ARR, and value delivered to users.
That's the part I keep coming back to. Plenty of teams are building software factories, but nobody wants to answer what the input to the factory is, what goal it's actually optimizing. So I asked him the uncomfortable version: when your AI decides what "good" looks like, what philosophy is it following?
His answer was to move the measurement. The factory should iterate on the business outcome, not on the PR count. When building gets cheap, the moat moves to how fast you can iterate, and the bar for what the product has to be keeps going up.

The divergence Patibandla describes: engineering output (upper curve) climbing while adoption, retention, and revenue (lower curve) stay roughly flat.
Session replay is a video for humans and a tree for agents
The mechanism underneath Amplitude's experiment is the interesting part. Product analytics has always started the same way: instrument every piece of the product, collect everything, then read quantitative metrics to see which surfaces are working. The instrumentation step is the tax.
Amplitude's bet is that an AI can skip it by watching session replays collected through the SDKs, along with friction signals that come for free: dead clicks, error clicks, and the rest of the interaction stream. The format question turns out to matter more than the capability:
And what we are noticing is actually all this telemetry, where you actually collect the DOM, or accessibility tree, that's too much for a human to understand.
Session replays are videos, which is the right format for a human and the wrong one for an agent. Hand a model the accessibility tree instead and the volume stops being a problem. It's exactly the kind of structured sprawl a model reads well. Patibandla says that with nothing more than the replay data as an accessibility tree plus whatever it can learn about the company from the web, the system formalizes the areas of the product, what users are trying to accomplish in each one, and how each area ties back to that customer's business.
What it finds first is your own regression
The example he reached for was small on purpose. A customer had an AI transcribe feature buried behind a triple-dot menu:
One of the customers, for example, they had this AI transcribe thing and then that AI feature was actually hidden behind like a triple dot and nobody was even realizing that it's there. And there was an easy suggestion that like, hey, maybe this is something you could do. And then that's an easy PR.
The suggestion is trivial; the watching is the expensive part. Ask a human to catch that and you're asking a PM to spend their week on replays. What Patibandla is describing instead:
Now the luxury would be like, you'll have some always on PM, some always on growth, engineer or UX designer, yeah, looking at it and making sure that your critical parts and then your core value drivers are not degrading as you are shipping this product.
That's observability and acceptance testing applied to product decisions, where the agent catches a regression in prod. And the regressions it caught inside Amplitude were the self-inflicted kind:
A lot of times, what we actually noticed where AI flagged and surprised us was actually these frictions that got introduced because we were doing some feature where we are assuming that we're actually improving this thing, but unintentionally degraded something else.
Nobody instruments the thing they didn't mean to break.
The inverse is where I'd expect this to go wrong first, and Patibandla didn't claim otherwise: an accessibility tree tells you a control went unused or a click went dead, not why. A user pausing to read looks a lot like a user stuck, and a feature nobody touches may be the one feature that keeps ten accounts from churning. The suggestion is cheap to generate and the judgment about whether to act on it still isn't.
Cheap to build, expensive to navigate
The failure mode on the other side of all this speed is a product that grows faster than anyone can hold in their head. As development gets faster, it becomes easy to widen the surface area and pile decision fatigue onto the end user. Patibandla on where the difficulty went:
So previously, when it is hard to build, it always used to add as this force to make people pause and think hard, like, hey, is this really necessary? Now when it's super easy, it's easy to just say, okay, fine, go ahead. I can just give the prompt and the feature will come out. Then the complexity shifts to the other side.
Cost used to do the triage for you. It doesn't anymore, and it's easy to add slop, so the pause has to be put back deliberately — a gate in the PDLC that asks whether a feature is worth the weight it adds to the experience before it ships, not after. In practice that looks like shipping it behind a flag with a named metric attached, and agreeing in advance what result would make you remove it. What I try to build toward on the other side of that gate:
I like to try and make experiences that feel more like a ladder and less like a jungle gym and how customers need to navigate it, like reduce the choices that they need to make along the journey, at least in the critical path, and simplify and trim.
A ladder also happens to be easier to measure: one path through the product is a funnel you can read, where a jungle gym is a graph nobody has time to interpret.
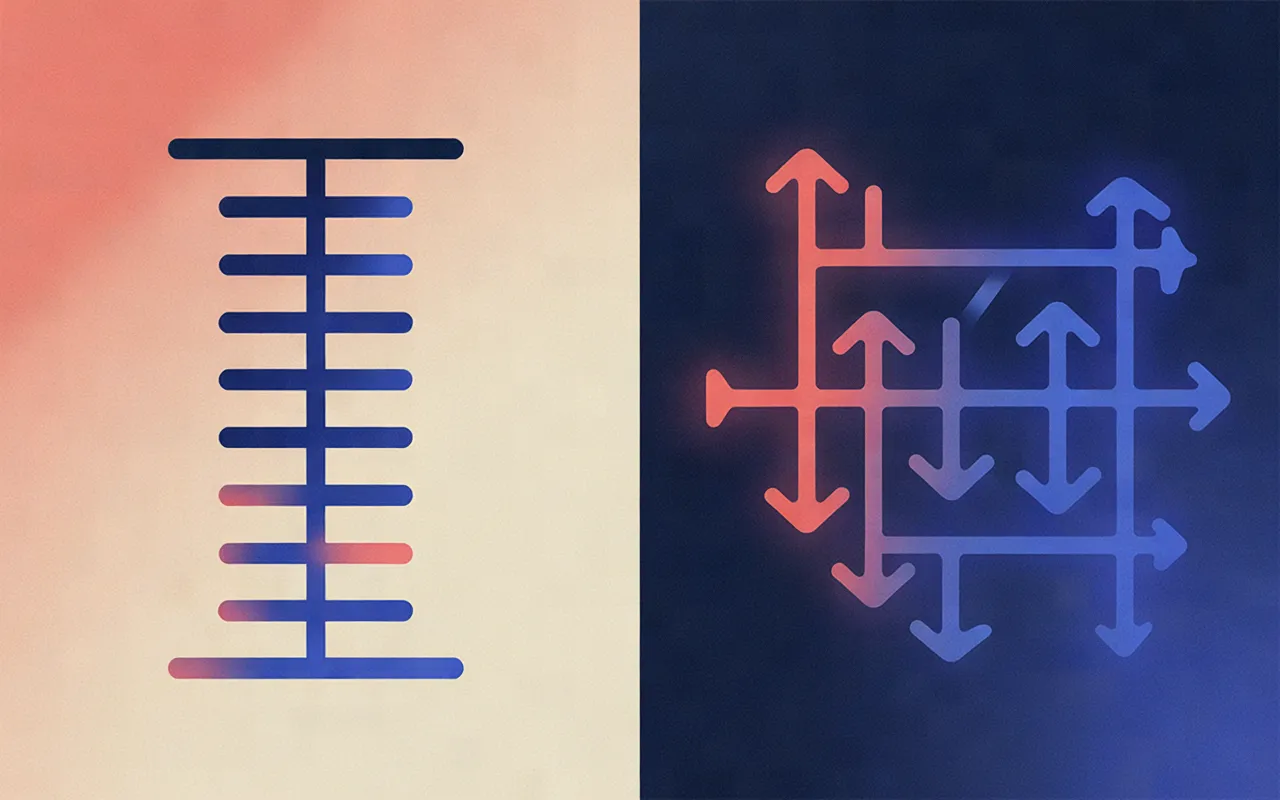
A single critical path versus a branching one: the left is a funnel you can read in your analytics, the right is a graph nobody has time to interpret.
The loop only closes if something acts on it
An insight nobody ships is just a dashboard. Amplitude's answer is the rest of its own product line: experimentation and feature flagging to roll a change out safely, guides and surveys to keep collecting feedback from users as it goes. The AI sits at the front of that chain as an always-on PM or user researcher, spotting the opportunity and handing it to coding agents to push. Recommendations like these can also teach builders what to aim at in the first place: this is blocking adoption, this is interrupting the core value loop.
He was careful about the maturity: early days, promising signals, not a solved problem. Agentic surfaces are also showing up inside his customers' products at the same time, which means the thing being measured is getting harder to instrument by hand just as the instrumenting gets automated. Amplitude's response is to try to be the place all that context lands, and to build the harness that automates the product work on top of it.
What engineering leaders should take from this doesn't depend on whether Amplitude's experiment pans out. If your throughput tripled and nothing downstream moved, you have a measurement problem sitting in front of a product problem. Put the PR count and one adoption or retention number on the same slide in your weekly review. If the gap between the two lines is the story every week, the factory is running fine and it's pointed at the wrong thing.
This interview was recorded at ELC 2026.